Ask most M&E officers where their logframe indicators live and you'll get two answers: the official logframe or Theory of Change document — usually a PDF or Word file signed off with the donor — and a separate indicator-tracking spreadsheet that someone maintains by hand, pulling numbers from survey exports every reporting cycle. The two are supposed to be the same thing. In practice, they diverge almost immediately, because nothing forces them to stay connected. A question gets renamed in the form. A target gets revised in a donor email and updated in the spreadsheet but not the logframe. A new field officer joins and re-derives an indicator slightly differently than their predecessor did. By the second or third reporting period, nobody is fully confident the indicator-tracking table reflects what the raw data actually says.
This article is about closing that gap: mapping individual survey questions to logframe indicators explicitly, building an indicator-tracking table that means something, and structuring your analysis tooling so the numbers come from the data directly instead of being manually re-typed into a disconnected sheet.
The Disconnect Between Your Logframe and Your Data
A logframe (Logical Framework) or Theory of Change organises a programme into a causal chain: activities produce outputs, outputs contribute to outcomes, outcomes contribute to longer-term impact. Each level typically has one or more indicators with a defined target and a reporting frequency. The problem is that a logframe is a planning document — it describes what you intend to measure, not how. The "how" — which exact survey question, which calculation, which denominator — usually lives only in the head of whoever built the original data collection instrument, and that knowledge doesn't transfer cleanly when staff change.
The result is a familiar failure mode: at report time, someone opens the raw data export, tries to remember (or reverse-engineer) which question corresponds to "% of households with improved water access," makes a judgment call about how to calculate it this quarter, and the number that ends up in the donor report may or may not match how it was calculated last quarter. Nobody is being careless — the system simply has no enforced link between the indicator definition and the data source.
Mapping Survey Questions to Indicators, Level by Level
The fix starts with an explicit mapping exercise, done once and maintained deliberately, that connects every logframe indicator to the exact question (or combination of questions) that produces it.
Output-Level Indicators
Output indicators are usually the most direct to map — things your programme directly produces: number of training sessions delivered, number of beneficiaries enrolled, number of health camps conducted. These typically map to a single form or a single count field, often collected through a programme monitoring form rather than a household survey. Mapping is straightforward: one indicator, one data source, minimal calculation.
Outcome-Level Indicators
Outcome indicators measure change in behaviour, knowledge, or condition among the people your programme reaches: household income, reported practice adoption, reading proficiency, vaccination completion. These usually map to specific questions in a household or beneficiary survey, and often require a calculation — a percentage of respondents meeting a threshold, an average across a subgroup, or a composite built from multiple questions (for example, a food security indicator built from a set of frequency questions). This is where mapping needs the most care: the calculation logic has to be documented, not just the source question.
Impact-Level Indicators
Impact indicators sit furthest from your programme's direct control and are typically measured less frequently — at baseline and endline, or annually — and sometimes draw on secondary data (government statistics, census figures) alongside your own survey. Because these indicators are collected less often and are more exposed to external factors, the mapping documentation should explicitly note the reference period and any assumptions about attribution versus contribution.
Building a Real Indicator-Tracking Table
An indicator-tracking table that actually works needs more columns than most spreadsheets in circulation. At minimum:
| Indicator | Level | Data Source (Question/Calc) | Target | Actual | Frequency |
|---|---|---|---|---|---|
| Households trained in improved practice | Output | Attendance form, count of unique household IDs | 1,200 | 1,340 | Quarterly |
| % of trained households adopting practice | Outcome | Follow-up survey Q14 ("Are you currently using...") = Yes / total trained | 60% | 52% | Bi-annual |
| % of children reading at grade level (Std 3) | Outcome | ASER-style reading assessment, categorical response mapped to grade-level threshold | 70% | 63% | Annual |
| Household income (median, real terms) | Impact | Baseline/endline survey income module, deflated by CPI | +15% vs baseline | Pending endline | Baseline/Endline |
Notice the "Data Source" column does real work here — it names the exact question and, where relevant, the calculation, not just "the survey." This is what makes the table auditable: anyone can trace a reported number back to the specific field it came from, without having to ask the person who built it.
Why the Spreadsheet Approach Breaks Down
Even a well-built indicator table in a spreadsheet has a structural weakness: the "Actual" column has to be filled in by hand, every reporting period, by someone pulling numbers from a separate data export. This manual re-entry step is where most of the drift happens — a wrong filter applied, a stale export used, a formula copied down incorrectly. It also means the tracking table is only ever as current as the last person who updated it, and it carries no audit trail connecting a reported figure back to the underlying submissions that produced it.
Spreadsheets aren't the problem — manually re-deriving numbers from raw data and typing them into a second system, every reporting cycle, is. Any step where a human re-types a number that already exists somewhere else is a step where the two numbers can silently diverge.
Structuring Dashboards to Mirror the Logframe Directly
The more durable fix is to build your cross-tabulation and dashboard tooling around the same structure as your logframe, so the "Actual" figure is generated directly from submitted data rather than re-typed. In practice, this means setting up a cross-tab or chart for each outcome-level indicator that mirrors its definition exactly — same question, same threshold, same denominator — and refreshing it against live submissions rather than a quarterly export.
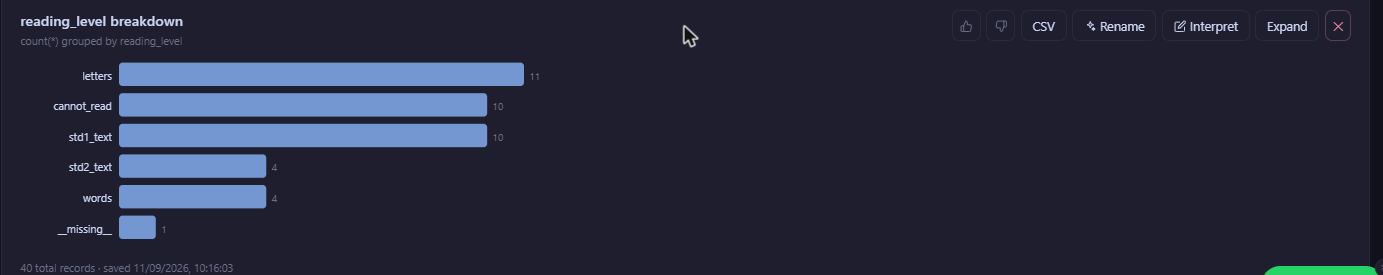
Take a reading-level assessment as an example. If your logframe outcome indicator is "% of children reading at Standard 1 text or above," the underlying data is a categorical variable (letters / words / Std 1 text / Std 2 text, in the ASER-style convention). Rather than exporting this to a spreadsheet and manually calculating the percentage above threshold every reporting cycle, a cross-tab built once — categorical breakdown with the threshold grouping applied — becomes the live source for that indicator. FieldGovern's Analyzer (TableForge) lets you build these cross-tabs once against your form's actual fields and refresh them as new submissions sync in, rather than re-deriving the number from scratch each time. The same approach extends to outcome indicators that require a filtered percentage, a subgroup breakdown, or a comparison across programme arms — each becomes a saved table structured to match its logframe definition, not a one-off spreadsheet formula.
This doesn't eliminate the indicator-tracking table — donors and boards still expect a clean summary document — but it changes where the "Actual" numbers come from. Instead of a person re-deriving them from an export, the summary table is populated from tables that are already structurally identical to the indicator definitions, cutting out the step where drift creeps in.
Common Ways Indicator Mapping Goes Wrong
Even teams that do the mapping exercise properly at the start of a programme tend to lose it in the same handful of ways over time. Knowing the failure pattern in advance makes it much easier to catch.
Composite Indicators Split Silently
Many outcome indicators aren't a single question — they're a composite built from several. A food security indicator might combine four or five frequency questions into a single score with defined cutoffs; a "meaningful practice adoption" indicator might require a respondent to answer yes to two of three related questions. When one of the underlying questions gets edited, reworded, or dropped in a form update, the composite calculation quietly breaks — sometimes the indicator keeps producing a number, just a wrong one, because the formula silently treats a missing field as a "no" rather than raising an error. Document the composite formula explicitly, including how missing responses to any component question should be handled, not just the final threshold.
Denominators Drift Between Reporting Cycles
"% of households with improved water access" sounds like a stable indicator, but the denominator behind it is a decision: all households ever enrolled, only households currently active in the programme, or only households reached in the current reporting period. Different staff, working from the same raw data, can legitimately produce different percentages depending on which denominator they use — and unless that decision is written down next to the indicator definition, the number will shift depending on who calculates it that quarter, with no one able to say which version is "correct."
The Same Indicator Gets Reused Across Programmes With Different Meanings
Organisations running several programmes often reuse a familiar indicator name — "household income," "beneficiary satisfaction" — across different logframes without realising the underlying question, reference period, or calculation differs between them. This becomes a real problem the first time someone compares indicator values across programmes in a portfolio-level report, because the numbers aren't actually measuring the same thing despite sharing a label. Naming an indicator explicitly with its programme and version ("HH Income (Programme X, v2)" rather than just "HH Income") avoids this confusion at the point where it's cheapest to fix — the mapping table itself.
Keeping the Mapping Alive: A Checklist
None of this requires abandoning the reporting formats donors expect. It requires making sure the numbers that land in those formats trace back, without manual intervention, to the raw data your enumerators actually collected.
Map Your Logframe Directly to Your Data
FG Analyzer lets you build cross-tabs and indicator tables directly against your form's fields, so your logframe tracking stays current as submissions sync in — no manual re-entry required. Start a free trial to try it on your own indicators.
Start Free Trial